LLM Sept 2026
RLCR from Scratch: A One-Pass Decision Model with Honest Probabilities
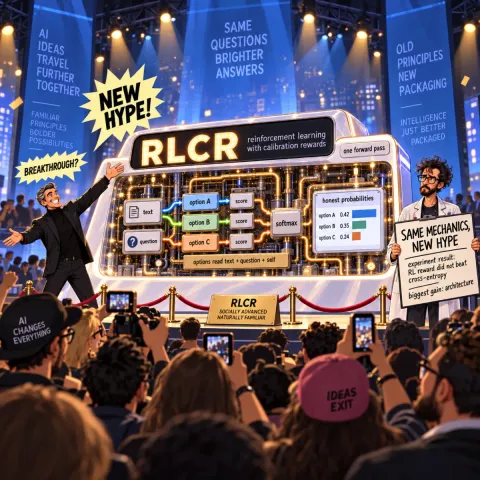
A model reads a support ticket, picks a department, and returns 0.94. RLCR — training that number with a reward only an honest probability can maximise — and a small typed-decision model built from an ordinary encoder: one forward pass, every option a parallel branch, and the same weights trained seven ways to find out what the reinforcement learning actually adds.